8 Materialization and Functions
1. Materialization
Materialization means saving an intermediate row set so that it can be used again, often more than once. The saved result can live at different scopes: inside one query, for a session, or as a database object.
Most executor nodes work as a pipeline. A parent asks a child for the next row, and the request propagates down the plan tree. Some nodes, however, need to consume a complete input, save it, and read the saved result repeatedly. PostgreSQL uses the Materialize node for this purpose.
A materialized row set is kept in backend local memory while it fits within the memory budget available to the operation. If it grows beyond that budget, PostgreSQL uses temporary storage. temp_file_limit limits temporary-file space used by an individual PostgreSQL process, including any parallel worker processes active within a single client session.
In the figure below, the upper Nested Loop has no efficient parameterized access to its inner input. That inner input is itself produced by another operation.
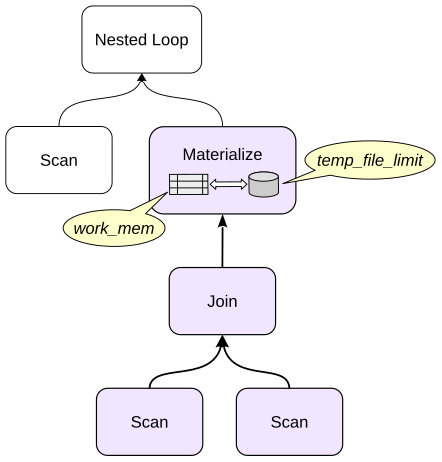
Recomputing it for every outer row would be wasteful, so PostgreSQL can materialize it once and rescan the saved rows.
For example, find pairs of airports where one airport uses Moscow time and the other lies beyond the Arctic Circle:
There is no useful index for the inner predicate in this example. Reusing the small inner result is cheaper than scanning and filtering it again for every outer row.
CTE Materialization
Common table expressions (CTEs), also known as WITH subqueries, are a great way to structure a query and make it more readable. Unlike regular subqueries, using CTEs does not lead to deep nesting.
Whenever possible, the planner folds a CTE into the parent query instead of materializing it. This lets the planner choose an optimal join order.
By default, a CTE is materialized in the following cases:
The main query refers to the CTE more than once, so its result does not have to be computed repeatedly. In this case materialization can be disabled with
AS NOT MATERIALIZEDThe CTE has side effects, including data modification or calls to volatile functions, so the side effect happens exactly once. In this case materialization cannot be disabled
Materialization can always be forced with AS MATERIALIZED.
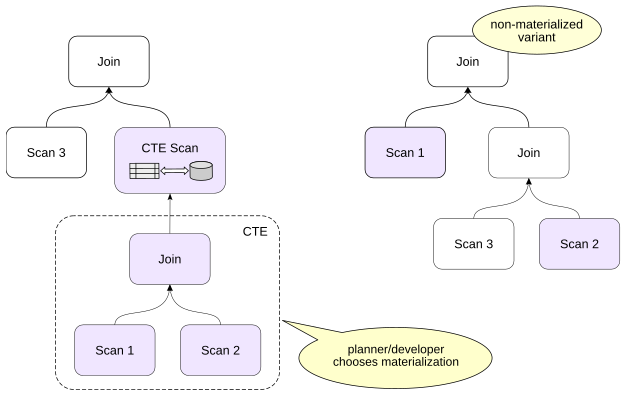
Consider a CTE used once:
There is no CTE Scan: the CTE was folded right into the main query.
Force materialization:
The CTE is now planned as a separate unit, and the parent query reads it through CTE Scan. Materialization is often a good choice when an expensive result is reused. But it can be disastrous if the parent query needs only a tiny fraction of a large CTE.
For example:
The entire bookings table is materialized even though the parent query asks for one key. Now allow the two references to be optimized independently:
The planner can now push the key restriction into both scans and use the primary-key index. Compare the Buffers values with the previous variant.
However, if a CTE modifies data, it is materialized in any case: the modification must happen exactly once.
Temporary Tables
If data has to be reused by several queries, it cannot be computed in a CTE for all of them, but it can be placed in a temporary table and used by those queries. Temporary tables have several useful properties:
They belong to a session
ON COMMITcan preserve rows, delete rows, or drop the table at transaction endTheir data is not WAL-logged in the ordinary way
- Their buffers are backend local rather than part of shared buffers
They are not free. PostgreSQL still creates catalog entries and relation files.
Workloads that create and drop temporary tables at very high rates can create catalog and filesystem pressure. Some application ecosystems have historically carried PostgreSQL patches or specialized designs to reduce that overhead; this is an application-specific engineering issue rather than a reason to avoid temporary tables in general.
temp_buffers limits the amount of local buffer memory a session can use for temporary relations. Its value can be changed only before the session first accesses a temporary table.
Create a temporary table containing airports in the Northern Hemisphere:
The table is created in the temporary pg_temp schema.
It often makes sense to analyze a newly filled temporary table before using it in queries. A backend process’s local memory is not accessible to autovacuum processes, so vacuuming and analysis of temporary tables must be performed manually.
Compare the cardinality estimates before and after running the analysis:
Materialized Views
A materialized view is a named query result stored as a database relation. It can be queried like an ordinary read-only table.
Indexes can be created on a materialized view, but integrity constraints cannot be added: constraints must be checked on the base tables. PostgreSQL also collects planner statistics for a materialized view.
Unlike an ordinary view, the rows of a materialized view do not change when the base tables change. Refresh is explicit.
A full refresh can be expensive. Core PostgreSQL does not currently maintain materialized views incrementally row by row as their base tables change. The pg_ivm extension by Yugo Nagata implements incremental view maintenance for supported cases.
Create a materialized view over airports:
Create an index:
Now change a base-table value. In August 2025, Manas International Airport changed its IATA code from FRU to BSZ; the demo database lets us use that as a convenient example.
The stored materialized-view rows do not change. Synchronization is explicit; refresh the materialized view:
2. Functions
Volatility Categories
Every function has a volatility category. The category is a promise to the optimizer about how the function behaves.
VOLATILE is the default. A volatile function can return different results on successive calls with the same arguments and can have side effects. PostgreSQL must not assume that two calls are interchangeable.
STABLE promises that, for the same arguments, the function returns the same result throughout one statement and does not modify the database. Such a function can be executed once during query execution and the computed value can then be reused.
IMMUTABLE is stronger: for the same arguments the result is promised to be the same forever. Constant calls can therefore be folded during planning.
These are only permissions, not exact execution schedules. STABLE does not mean that every stable function is universally executed exactly once; it means that the optimizer is allowed to treat repeated same-argument evaluations as equivalent where the plan permits it.
Incorrect labels can produce incorrect results. Marking a function IMMUTABLE when it depends on time, configuration, table contents, or other changing state can freeze a stale value into a reusable plan.
Create a wrapper around random():
With the correct VOLATILE label, the predicate is evaluated for each row:
A run might return any subset of the ten rows:
Now lie to PostgreSQL:
In this plan the stable expression becomes a One-Time Filter, so the result is either all ten rows or none:
Marking the wrapper IMMUTABLE gives the planner even more freedom:
Two separate planning attempts can freeze different random outcomes. The surprising plans are not a PostgreSQL bug: we gave the optimizer a false contract.
Function Inlining
PostgreSQL can inline the body of suitable SQL-language functions into the surrounding query, both for scalar and set-returning functions. In both cases there are many restrictions: the function must be written in SQL, use a single SELECT statement, and satisfy other conditions. A scalar function must not access database tables or call functions with a less strict volatility category; a set-returning function must be STABLE or IMMUTABLE.
Inlining matters because it removes the function boundary from the planner’s point of view. Predicates from the outer query can then sometimes be pushed into the function body, and joins can be reordered across the former boundary.
The body of a simple scalar SQL function can be substituted directly into the main SQL statement immediately before planning. In that case, there is no function-call overhead.
For scalar SQL functions, restrictions include volatility consistency. A function declared STABLE cannot safely inline a body that invokes a volatile operation such as random(). With rnd() marked STABLE:
The wrapper remains visible.
Restore the truthful volatility:
Now the filter references random(), which is called directly, bypassing the rnd() wrapper.
Calling Set-Returning Functions
When a set-returning function appears as a table expression in FROM, PostgreSQL represents it with Function Scan. In this case all rows returned by the function are materialized first and only then passed to the parent plan node. This is a current implementation limitation.
When a set-returning expression appears in the target list, PostgreSQL uses ProjectSet and can produce rows on demand. SQL functions, most built-in functions written in C, and PL/Python functions that return an iterator work this way. Functions in other programming languages can use the same interface if the language implementation supports it.
The difference can be enormous under LIMIT. Call generate_series in FROM:
Now put the set-returning function in the target list:
In the first plan, Function Scan obtains all rows from the function before Limit is applied. In the second plan, ProjectSet produces ten rows—exactly as many as Limit requests.
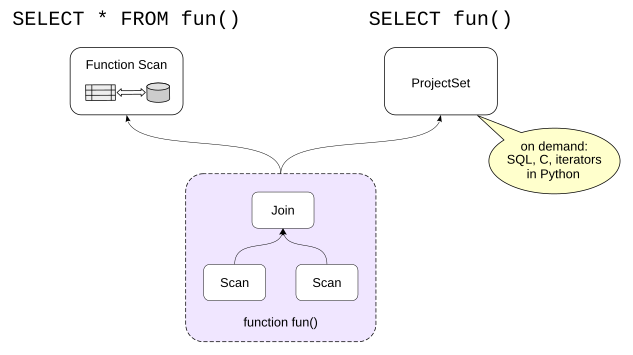
The query execution time decreases by orders of magnitude. The Result node represents the omitted FROM clause and passes exactly one row to its parent.
This does not mean that every function language can stream rows. PL/pgSQL set-returning functions, for example, currently materialize their complete result before returning it to the calling executor interface.
The plan still contains ProjectSet, but the function implementation has already done the expensive work before the first row can emerge. The execution time shows this clearly.
COST and ROWS
When a function cannot be inlined, the planner often has to treat it largely as a black box. CREATE FUNCTION lets us provide two important estimates.
COST is the estimated execution cost in units of cpu_operator_cost. For a set-returning function, it is the cost per returned row. The default is 1 for C-language and internal functions and 100 for functions in other languages.
ROWS is the estimated number of rows returned by a set-returning function. The default is 1000.
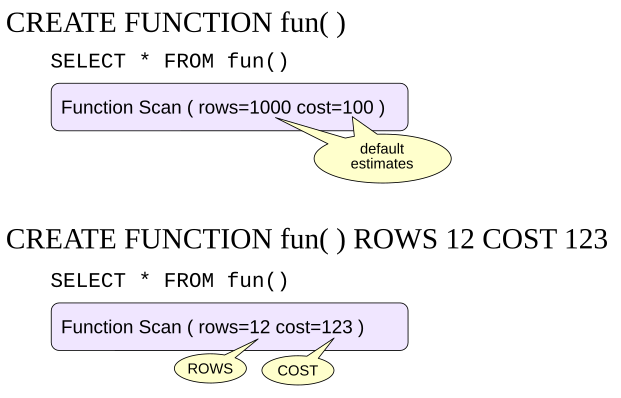
Create a PL/pgSQL function that returns the days of the week:
The query plan:
The server estimates the cardinality of this function’s result as 1000 rows, although the actual value is seven.
The startup component reflects the function-cost estimate:
Raise the function cost:
Set the expected number of rows returned by the function:
The resulting estimated cost is:
Check these values in pg_proc or via the meta-command:
Planner Support Functions
The COST and ROWS clauses let us specify function cost and row count as constants. Fixed values are not always good enough, however.
In PostgreSQL, a target function can have a planner support function that supplies the planner with information that depends on the argument values of the target function.
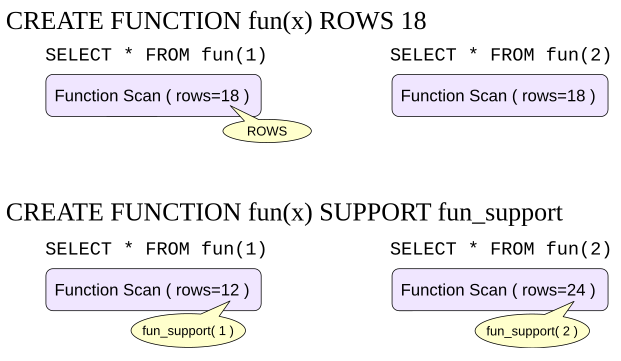
A support function can provide, among other things:
An estimate of the function’s cost
An estimate of the number of rows returned
An expression equivalent to the function call
For boolean functions, it can additionally provide:
A selectivity estimate
An equivalent predicate that uses an indexable operator
Planner support functions use PostgreSQL’s internal planner API and currently must be written in C.
Parallel-Safety Labels
Not every query can run in parallel. The planner cannot safely infer every possible effect of a user-defined function. Parallel execution therefore relies on an explicit function label.
A function can be:
PARALLEL UNSAFE: its presence prevents a parallel plan for the queryPARALLEL RESTRICTED: it can participate in a query that uses parallelism, but it may execute only in the parallel group leaderPARALLEL SAFE: it may execute in parallel workers
The default for user-defined functions is PARALLEL UNSAFE. Parallel-safety labels are also specified for user-defined aggregate functions.
All basic standard functions are parallel safe.
The exact counts depend on installed extensions and PostgreSQL minor version.
psql also shows the label:
Now create a function that sums segment prices for one ticket:
Use it in one subquery and compare that total with the total booking amount from another subquery:
With the function marked safe, both subqueries can use parallel plans.
Mark it unsafe:
A single unsafe function disables parallel query for the statement.
Now mark it restricted:
The subquery that calls the restricted function must run in the leader, while the independent bookings subquery can still use parallel workers.
The safe label is not merely a performance hint. Mislabeling a function can cause errors or wrong answers. When in doubt, use the stricter label.
Referenced resources
- github.com/sraoss/pg_ivm
- postgrespro.ru/docs/enterprise/16/sql-createfunction
- wiki.postgresql.org/wiki/Inlining_of_SQL_functions
- www.postgresql.org/docs/18/parallel-safety
- www.postgresql.org/docs/18/queries-with
- www.postgresql.org/docs/18/sql-creatematerializedview
- www.postgresql.org/docs/18/sql-createtable
- www.postgresql.org/docs/18/xfunc-optimization
- www.postgresql.org/docs/18/xfunc-volatility