6 Statistics
1. Basic Statistics
PostgreSQL collects basic planner statistics at two levels: for the relation as a whole and for individual columns.
Table-Level Statistics
Relation-level statistics include the estimated size of the relation: the reltuples and relpages columns of pg_class. These values matter enough that PostgreSQL updates them not only during VACUUM and ANALYZE, but also after some DDL operations such as CREATE INDEX and CREATE TABLE AS.
The planner can also scale the stored row count estimate when the current physical file size differs from the relpages value on which that estimate was based. This lets the estimate react to table growth even before the next full statistics refresh.
ANALYZE examines a random sample of rows rather than reading the entire table for every column statistic. The required sample size is not growing with the table, and is set by default_statistics_target (100 by default), multiplied by 300.
For a large table, estimates derived from a sample will not be exact. The planner usually needs an estimate accurate enough to distinguish competing plans. An order-of-magnitude mistake can be disastrous; a small sampling error often is not.
Consider a query with no predicate:
The row estimate comes from pg_class:
In this case it happens to match the exact count:
The remaining basic statistics are collected per column by ANALYZE. Their internal representation is stored in pg_statistic; the pg_stats view presents the most useful fields in a friendlier and privilege-safe form.
Fraction of Null Values
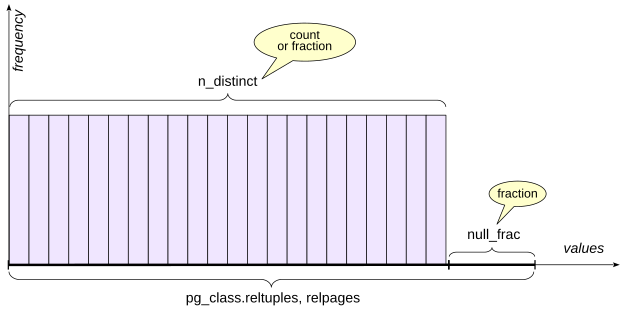
pg_stats.null_frac stores the fraction of rows in which the column is null, ranging from 0 to 1.
Some flights have not departed yet, so actual_departure is still null:
The planner obtains the estimate by multiplying the relation row count estimate by null_frac:
The exact value is close but not identical:
Number of Distinct Values
pg_stats.n_distinct stores an estimate of the number of distinct non-null values in a column. A positive value is an estimated absolute count. A negative value represents the ratio of distinct values to rows. For example, −1 means that all values are unique, which is typical for a primary key. The negative representation is useful because it scales naturally as the table grows.
Most Common Values
If every value occurred with the same frequency, the number of distinct values would already tell us a great deal about equality predicates. Real data is rarely so cooperative. PostgreSQL therefore stores two more pieces of information:
pg_stats.most_common_vals: an array of the most common values, also called the MCV list
pg_stats.most_common_freqs: an array of their frequencies
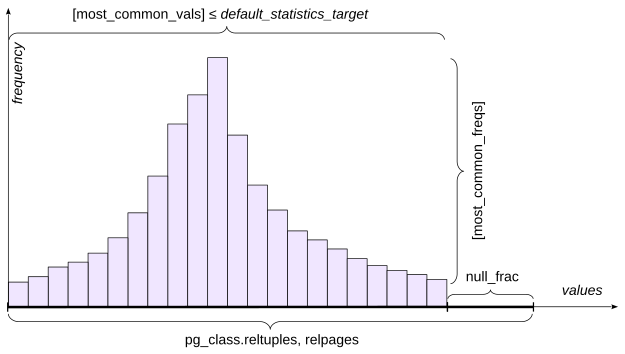
For a value that appears in the MCV list, its stored frequency can be used directly as the selectivity estimate. The maximum number of entries is controlled by the statistics target. default_statistics_target supplies the default, and ALTER TABLE ... ALTER COLUMN ... SET STATISTICS can override it for an individual column. Increasing a target also increases the sample size used by ANALYZE.
To avoid increasing the size of pg_statistic and burdening the planner with useless work, values larger than 1 kB are excluded from statistics and analysis. Such large values are most likely unique and have little chance of appearing in most_common_vals anyway.
For an experiment, reduce the statistics target for the arrival airport:
Mumbai (BOM) is common enough to appear in the MCV list:
The exact count is also 55:
Inspect the most common values and frequencies:
The cardinality estimate is the number of rows in routes multiplied by the stored frequency:
MCV data also contributes to inequality estimates: PostgreSQL can sum the frequencies of MCV entries that satisfy the range condition.
If a value is not in the MCV list, the planner estimates it from the remaining population under a uniform-distribution assumption.
Santiago (SCL) does not appear in our ten-value MCV list:
The exact result is 18:
To obtain the estimate, the planner first sums the frequencies of the most common values:
The column has 73 distinct values:
Ten of them are already represented explicitly in the MCV list. With no nulls, the remaining probability mass is spread approximately uniformly over the remaining 63 values:
Histogram
When there are too many distinct values to describe usefully with an MCV list, PostgreSQL also builds a histogram.
A histogram consists of several buckets containing values. The number of histogram buckets is controlled by the same default_statistics_target parameter.
Bucket boundaries are chosen so that approximately the same number of values falls into each bucket; in the figure this is shown by rectangles of equal area. With this construction, PostgreSQL only needs to store the array of boundary values in pg_stats.histogram_bounds. The frequency of one bucket is 1/number of buckets.
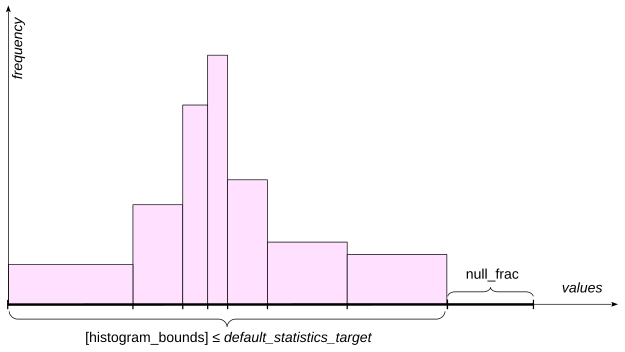
For an inequality such as field < value the planner estimates how much of the histogram lies to the left of the boundary value. It can interpolate within the containing bucket rather than counting only whole buckets.
The MCV values and nulls are excluded from the histogram population:
That is why range selectivity combines information from both the MCV list and the histogram.
Consider:
The exact count is:
The MCV values inside the requested interval contribute this frequency:
DFW is exactly the right boundary of the second bucket in this example, so two of ten histogram buckets lie in the interval. There are no nulls. The estimate is therefore:
For a boundary inside a bucket, PostgreSQL refines the estimate with interpolation appropriate to the data type and operator.
A histogram is much less useful for an equality condition on a value that is not in the MCV list. In that case PostgreSQL falls back to an estimate based on the remaining number of distinct values.
Additional Statistics Fields
Several other statistics fields affect planning.
pg_stats.correlation measures statistical correlation between the logical order of column values and the physical order of rows. Values near 1 or −1 indicate strong physical ordering; values near zero indicate little correlation. This matters when costing index scans because strong correlation reduces expected random heap access.
pg_class.relallvisible stores the number of table pages marked all-visible in the visibility map. An all-visible page is one all of whose tuples are known to be visible to all current and future transactions. If this number is not large enough, the planner may choose a bitmap scan instead of an index-only scan.
pg_stats.avg_width stores the average size of values in the column, in bytes, for estimating the memory required by an operation.
Custom and Generic Plans
With the simple query protocol (see Chapter II, “Planning and Execution”), a statement is normally parsed, planned, and executed as a new statement each time.
The extended protocol allows statements to be prepared, and those statements can have parameters. The parse tree is kept in the local memory of the backend process. Planning can then happen later when parameter values are known.
A custom plan is generated for one execution using its actual parameter values. This is useful when data is skewed, because different parameter values can make different access methods optimal. For example, an index may be excellent for a rare value but worse than a sequential scan for a very common value.
A generic plan is created without using the actual parameter values. It can be reused across executions and therefore saves planning time. A generic plan works especially well with a uniform distribution, when the selectivity of a condition does not depend on the particular parameter value.
Prepare a query and create an index:
Cancelled flights are rare enough for an index scan:
Arrived flights are common, so a custom plan chooses a sequential scan:
Execute the statement three more times so that the total number of custom executions reaches five:
The counters are visible in pg_prepared_statements:
On the next execution this example switches to a generic plan. A generic plan shows parameter symbols instead of concrete values:
For skewed data this switch can be undesirable. To handle it, plan_cache_mode can override the automatic heuristic:
2. Extended Statistics
Basic statistics that are collected automatically may not be enough to produce accurate cardinality and selectivity estimates.
PostgreSQL allows the administrator to manually determine which additional—extended—statistics are needed. You can gather statistics that span multiple columns at once (multivariate statistics), or statistics on an arbitrary expression.
Note that basic statistics are collected for tables and their columns, but not for indexes, except for indexes on expressions. Therefore, creating an index on several columns does not by itself create multivariate statistics.
Extended statistics are created with the CREATE STATISTICS command. Their definitions are stored in pg_statistic_ext; collected data is stored in pg_statistic_ext_data.
There are several kinds of multivariate statistics available.
Functional Dependencies
A functional dependency describes how strongly values in one column determine values in another.
| city | index |
|---|---|
| Samara | 443000 |
| Kazan | 420000 |
| Nizhny Novgorod | 603000 |
| Veliky Novgorod | 173000 |
For example, if a postal code uniquely determines a city, predicates on city and postal_code are correlated, as shown in the figure.
Consider two predicates on routes:
Without extended statistics, the estimate is much too low:
The reason is that the planner assumes predicates are independent and calculates the resulting selectivity as the product of the selectivities of conditions combined with logical AND. This is visible in the plan: the estimate in the Bitmap Index Scan node for the route_no condition is correct, but after filtering in the Bitmap Heap Scan node by arrival_airport, it is underestimated. We know, however, that the route number uniquely determines the arrival airport, so the second condition is in fact redundant, assuming the airport is specified correctly.
Create dependency statistics:
Inspect the dependency:
The number after the colon is the measured degree of dependency for the attribute mapping. Now the estimate improves:
psql meta-command \d routes also lists statistics objects defined on the table. The Statistics objects section shows their names, columns, and nondefault statistics targets:
Most Common Combinations
Columns can be correlated without either functionally determining the other. The figure shows possible city-river pairs. The predicates on city and river are clearly correlated, but unlike the previous example neither column determines the other: cities and rivers have a many-to-many relationship.
| city | river |
|---|---|
| Samara | Volga |
| Kazan | Volga |
| Nizhny Novgorod | Oka |
| Nizhny Novgorod | Volga |
| Veliky Novgorod | Volkhov |
Here is a similar example in the demo database:
The planner underestimates the number of rows. With an MCV statistic on the pair the estimate is now correct:
The multivariate MCV data can be inspected with the pg_mcv_list_items function:
Distinct Combinations
Another situation in which the planner can make an error is grouping. Multivariate ndistinct statistics can improve estimates for grouping by several columns.
In the example in the figure, the number of possible combinations of all fields clearly cannot be determined by simply multiplying the number of distinct values in each column separately.
| city | region | index |
|---|---|---|
| Samara | Samara Oblast | 443000 |
| Kazan | Republic of Tatarstan | 420000 |
| Nizhny Novgorod | Nizhny Novgorod Oblast | 603000 |
| Veliky Novgorod | Novgorod Oblast | 173000 |
Count the distinct direct airport pairs:
Without multivariate distinct statistics, the planner badly underestimates the number of groups:
Create an extended statistics object. If no kind is specified, PostgreSQL includes all supported multivariate kinds that apply:
The estimate improves. Inspect the stored estimate:
\dX lists extended statistics objects. The values themselves are stored in the pg_statistic_ext_data view.
Statistics on Expressions
Extended statistics can also collect ordinary univariate statistics for an expression, much as if the table had a stored column containing that expression.
| city | index | address |
|---|---|---|
| Samara | 443000 | 443000, Samara |
| Kazan | 420000 | 420000, Kazan |
| Nizhny Novgorod | 603000 | 603000, Nizhny Novgorod |
| Veliky Novgorod | 173000 | 173000, Veliky Novgorod |
Expressions can also participate in multivariate statistics together with columns or other expressions.
Without expression statistics, a predicate whose operand is an expression may force the planner to use a generic default selectivity because it has no distribution data for the expression itself. For example:
The estimate is far too small. One way to provide statistics is an expression index, but an index costs storage and maintenance even if it is not needed for access. If the goal is only to improve estimates, create expression statistics instead:
The estimate is now close to the actual value.
Expression statistics are visible in the pg_stats_ext_exprs view:
Clean up the objects created in this chapter:
Referenced resources
- www.postgresql.org/docs/18/planner-stats
- www.postgresql.org/docs/18/planner-stats
- www.postgresql.org/docs/18/planner-stats
- www.postgresql.org/docs/18/planner-stats
- www.postgresql.org/docs/18/row-estimation-examples
- www.postgresql.org/docs/18/view-pg-stats